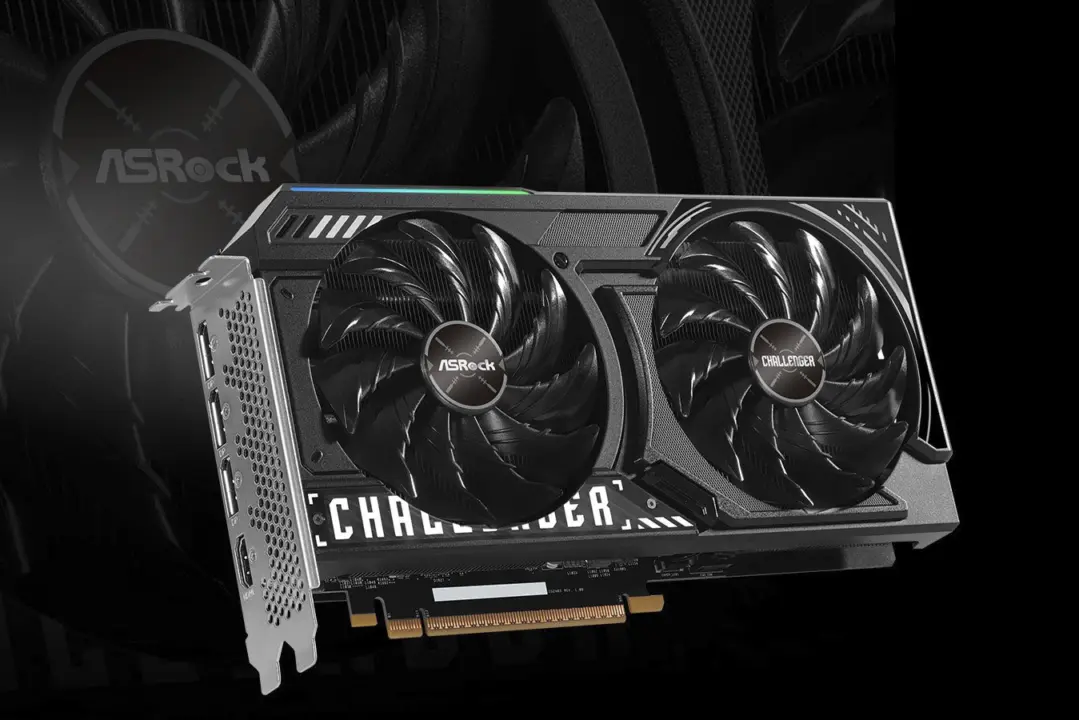
The Intel Arc B580 can now use large language models previously needed huge hardware. Latest benchmark shows the GPU in action on a 125 billion parameter AI model. It's so fast that even enthusiasts can use it locally with this speed.
XeStrata engine boosts inference speed by 185% on the mid-range GPU
This is proof mid-range consumer GPU can be used for heavy duty AI tasks, without having to reach into high end enterprise AI accelerators. This performance info is important for potential buyers wanting to run local open source AI applications.
- GPU Model: Intel Arc B580 Challenger 12GB OC
- VRAM: 12GB GDDR6
- System RAM: 64GB DDR5
- OS: Ubuntu 26.04 LTS
- AI Model: Qwen3.8-Flash-Next (125B parameters)
In this case the tested GPU was ASRock Intel Arc B580 Challenger 12GB OC. It was paired with Intel Core Ultra 5 250KF Plus processor. Ubuntu 26.04 LTS was used for the OS.
A massive 64GB DDR5 system memory was used for this heavy duty AI task. PC Watch tested the GPU with XeStrata, inference engine version 0.1.43-2. This makes it possible to run the Qwen3.8-Flash-Next model so fast on GPU.
XeStrata can crunch through 31.1 tokens per second on the Intel Arc B580. This is massive improvement for software support. To compare, the original Strata engine runs only 10.9 tokens per second on the same system.
This means XeStrata can execute things so much better with optimized execution paths. It also shows the full potential of Intel XMX matrix hardware. 12GB VRAM was not enough to hold the entire model. It used the 64GB system RAM to offload the weights.
125B model runs ~2.85 times faster with XeStrata compared to original generation speed, same GPU. It's not shown how much of this speed gain is from any one optimization in the given comparison. Tested version of XeStrata is older than the October 24th release of the project which also includes other changes.
We have been following Intel Arc B580 close. Including news on how to use Linux utility to increase VRAM window on old motherboards.
Intel Arc B580 can run big AI models. This is possible with software giving huge boost in speed for inference. This can be seen on XeStrata.
They're giving almost triple token crunching speed compared to the original Strata engine, on the same system. This shows how the GPU can run 125B parameter model. This is possible with both 12GB VRAM and system RAM in use. This benchmark gives information about running AI locally with mid-range Intel GPUs.
Source: NotebookCheck
Discussion
0 comments